How every number stays honest, and what has been measured.
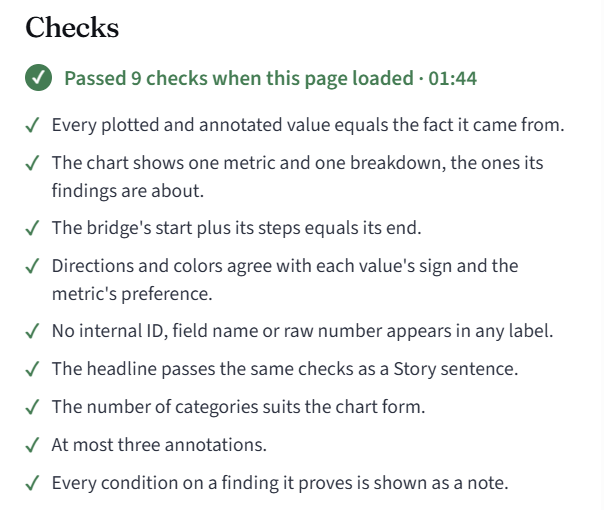
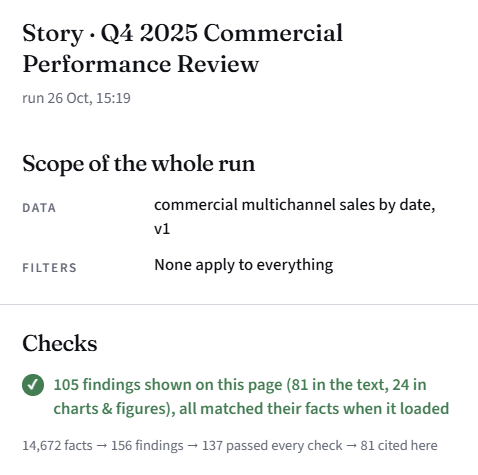
Every number is checked at three points before it is shown: the facts, the findings built from them, and the sentences written from those. Anything that fails is left out, never published. Below: the checks, then the scorecard, then what isn't measured yet.
Code computes every number
The run computes facts from the dataset's rows. Each fact is a number with what it measures, who it covers, its period and how it was worked out. The Story and the answers never compute a number of their own.
The AI chooses, code checks
For each question, the AI picks the findings a careful analyst would tell a business reader, by pointing at facts; it writes no numbers. Code then checks every finding: one measure, one population and one subject; a change cites a change, a share cites a share; a top list includes every member tied with the last one named; a trend needs six or more periods and two full years; a lift's figures are cited only by a finding about the lift. A finding that fails is dropped; one that links others is dropped with them.
The AI writes, code checks every sentence
Every sentence names the findings it rests on, and must pass: every number equals a value of its findings, at the precision written; each direction word ("rose", "fell") agrees with the sign of its number; every condition on its findings is said in that sentence or the next; it uses no word the evidence can't support, from a published list; it names at most four periods' values. A draft with problems gets one repair attempt. A sentence that still fails is left out. Where the evidence doesn't settle something, the answer says "Not settled by the evidence", and the Story lists it under What is open.
The scorecard
What has been measured on the October 2026 release, and the result. All of it was run on synthetic data: planted datasets generated with known answers, and two sample files. Nothing here was measured on a client's real data; that is part of what a pilot is for.
Are the numbers right? (no model involved)
Do the checks catch the AI?
Does it read the request right?
How long does it take?
All measured on the October 2026 release or the runs leading to it; rows measured on the release candidate were run again after the cut with identical results. The full scorecard, with each row's date, code and how to rerun it, is available on request.
Not measured yet. Every result above is on synthetic data; a pilot is the first test on a client's real data. Human judgment of the writing rests on a small hand-graded set, and how often every number matched its fact when read isn't recorded as a statistic.